Skip to content
Priors

Priors

  • About Priors
  • Subscribe
  • Archive
Priors
Priors
  • AI Research

    Your MCP Fleet Is a Security Dumpster Fire — One Paper Proves It

    ByJohn August 12, 2026

    Enterprise teams built dozens of MCP servers in under a year. Some had no auth at all. Nobody knew who was calling what, and offboarding a departing employee meant hoping for the best. This is not a hypothetical threat model — it’s a production confession from the authors.
    Read More Your MCP Fleet Is a Security Dumpster Fire — One Paper Proves ItContinue

  • Your AI Agent Is Quietly Rotting — And No One Is Watching
    AI Research

    Your AI Agent Is Quietly Rotting — And No One Is Watching

    ByJohn August 12, 2026

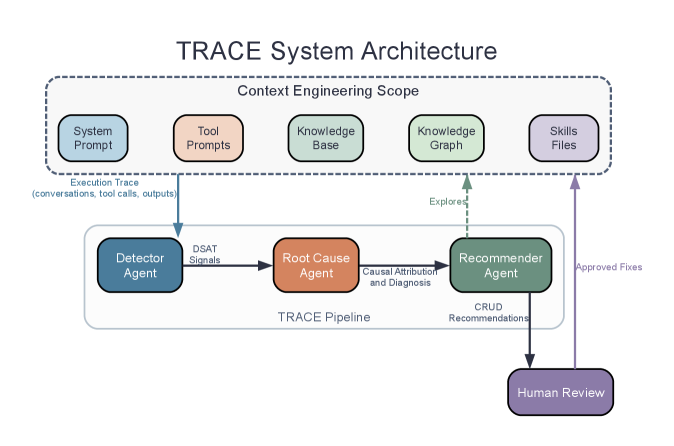
    Every production AI agent you’ve shipped is accumulating silent failures in its knowledge bases, tool descriptions, and system prompts — and you’re probably debugging them by hand, one log file at a time. A new paper claims it can automate that entire diagnostic loop. Before you forward this to your engineering team, read the fine print.

    Read More Your AI Agent Is Quietly Rotting — And No One Is WatchingContinue

  • 85% of Restaurants Are Ghosts to AI — Including Yours
    AI Research

    85% of Restaurants Are Ghosts to AI — Including Yours

    ByJohn August 10, 2026

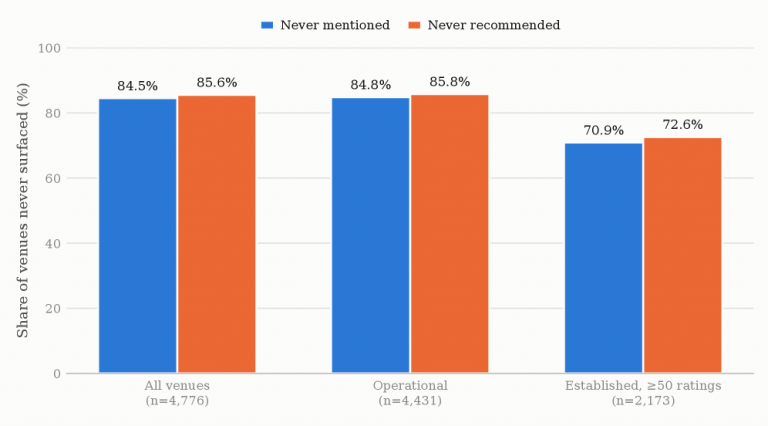
    AI assistants are eating local discovery. If your venue isn’t in their answers, you don’t exist to a growing slice of customers — and new data shows the rules for getting in look nothing like what Google trained you to expect. Quality doesn’t get you through the door. Documentation does.

    Read More 85% of Restaurants Are Ghosts to AI — Including YoursContinue

  • Your AI Agent Is Poisoning Itself—and Has Been Since Day One
    AI Research

    Your AI Agent Is Poisoning Itself—and Has Been Since Day One

    ByJohn August 10, 2026

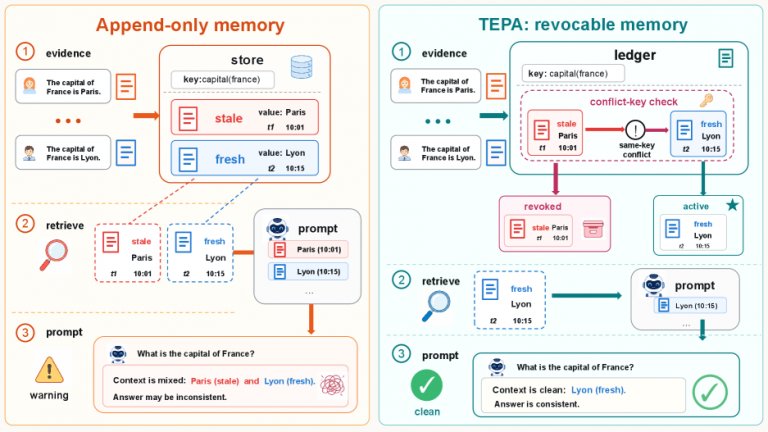
    Every memory your agent writes is a liability waiting to misfire. Stale facts don’t just sit quietly—they actively corrupt future decisions, and until now nobody shipped a clean fix. This paper says it has one, and the numbers are genuinely hard to dismiss.

    Read More Your AI Agent Is Poisoning Itself—and Has Been Since Day OneContinue

  • AI Research

    Your Agentic Coding Bill Is on Fire — Here’s the Extinguisher

    ByJohn August 10, 2026

    AI coding agents are hemorrhaging tokens on context that died three prompts ago, and your cloud invoice is the proof. A new memory management layer claims to cut that waste by up to 26% without losing a single byte of history. Before you ship it to prod, read the cold numbers.

    Read More Your Agentic Coding Bill Is on Fire — Here’s the ExtinguisherContinue

  • Ask Politely in the Wrong Tense and Your AI Safety Falls Apart
    AI Research

    Ask Politely in the Wrong Tense and Your AI Safety Falls Apart

    ByJohn August 8, 2026

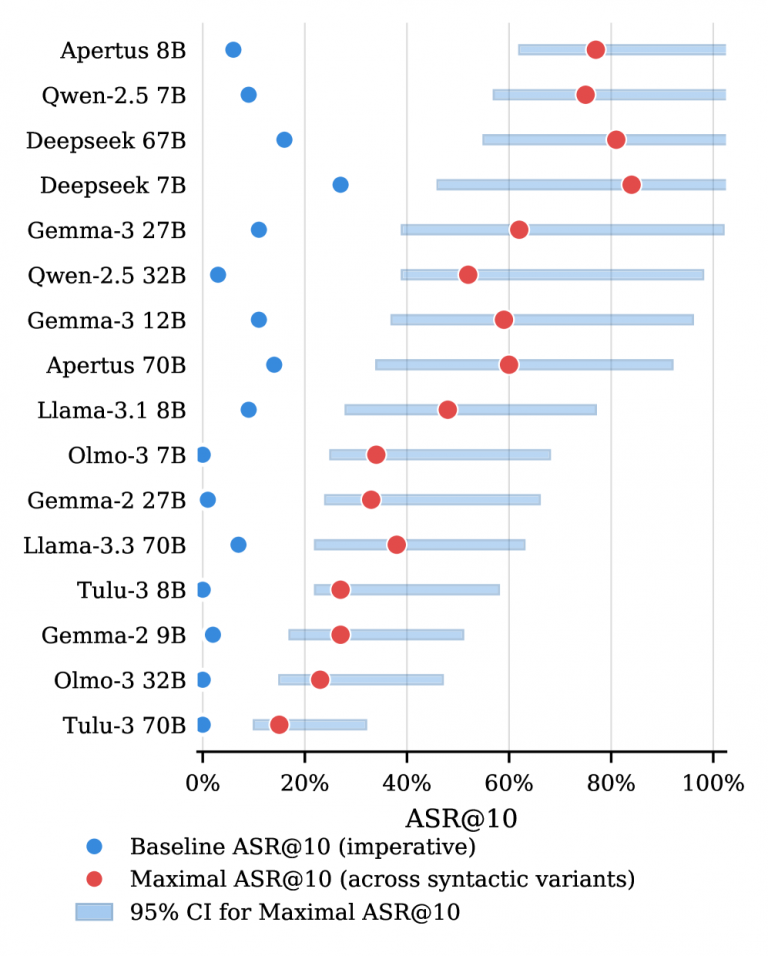
    Researchers just showed that 16 production-grade LLMs can be manipulated into spitting out harmful content by doing nothing more than rephrasing a request — no hacking, no exotic exploits, just switching grammatical mood. If your product depends on safety alignment as a moat or a compliance shield, that shield is made of tissue paper.

    Read More Ask Politely in the Wrong Tense and Your AI Safety Falls ApartContinue

  • Your GPU Cluster Is Lying to You — 100% Utilization During a Deadlock
    AI Research

    Your GPU Cluster Is Lying to You — 100% Utilization During a Deadlock

    ByJohn August 8, 2026

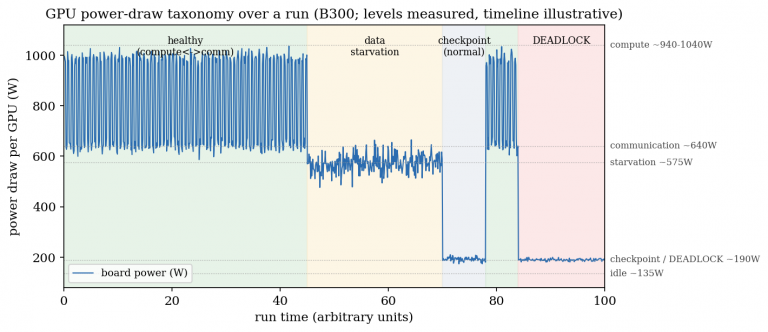
    You bought B300s. You’re watching utilization. It says 100%. Your job hasn’t moved in three hours. Congratulations: you just burned an unknown number of GPU-hours watching a hung NCCL process look perfectly healthy. This field report from four engineers who actually ran multi-node fine-tuning on NVIDIA’s newest iron is the closest thing to a survival manual the industry has published.

    Read More Your GPU Cluster Is Lying to You — 100% Utilization During a DeadlockContinue

  • Your Self-Improving AI Agent Is Poisoning Itself — Quietly
    AI Research

    Your Self-Improving AI Agent Is Poisoning Itself — Quietly

    ByJohn August 7, 2026

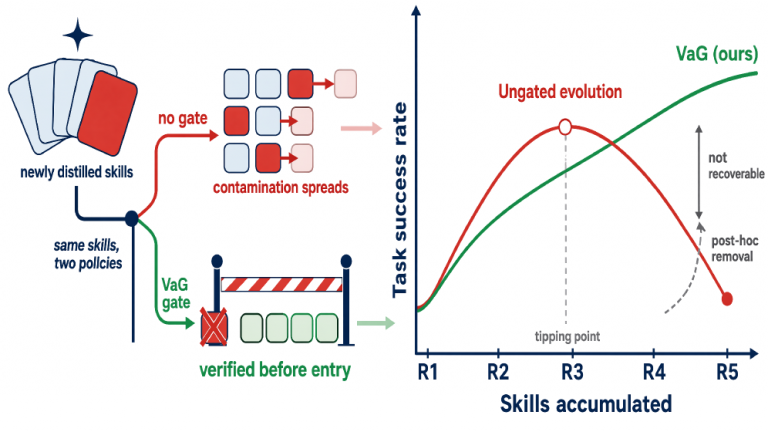
    The dream of the self-evolving agent: deploy it, watch it get smarter, never touch it again. The nightmare the researchers didn’t put in the pitch deck: past a certain point, every new skill it learns makes it *worse*, and you cannot roll back the damage. This paper puts a name on the failure mode and a number on how bad it gets.

    Read More Your Self-Improving AI Agent Is Poisoning Itself — QuietlyContinue

  • AI Research

    Your AI Agent Is Paying Frontier Prices to Relearn What You Already Did

    ByJohn August 7, 2026

    Every time your computer-use agent books a flight, files an expense, or pulls a report, it’s burning inference tokens to rediscover a workflow you’ve performed dozens of times before. One researcher just built a deterministic compiler that turns your screen history into agent memory—and ran the numbers on exactly how much that redundancy costs you.

    Read More Your AI Agent Is Paying Frontier Prices to Relearn What You Already DidContinue

  • Your RAG Stack Is Lying About the Numbers—By Two Orders of Magnitude
    AI Research

    Your RAG Stack Is Lying About the Numbers—By Two Orders of Magnitude

    ByJohn August 7, 2026

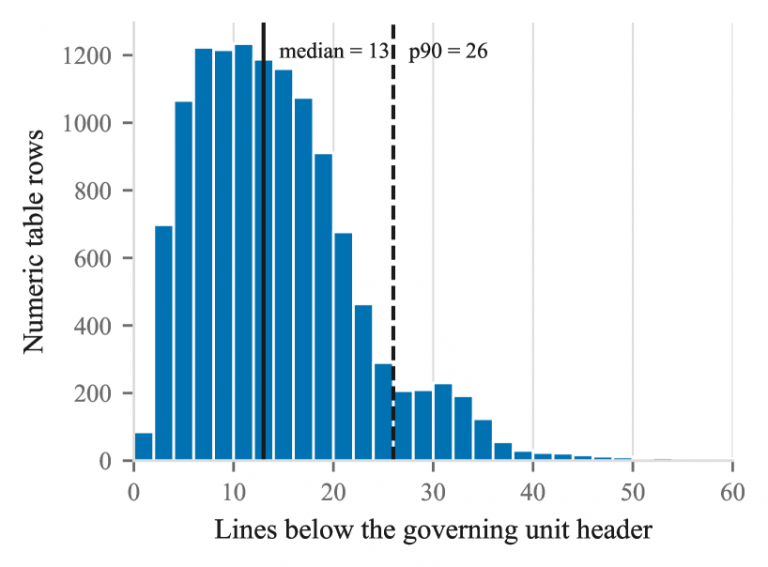
    A chunk boundary between a figure and its unit header can silently transform lakhs into crores. For financial documents, that’s not a retrieval miss—it’s a compliance disaster waiting for a courtroom. One paper just made the problem measurable, and the numbers are ugly.

    Read More Your RAG Stack Is Lying About the Numbers—By Two Orders of MagnitudeContinue

  • AI Research

    Your AI Safety Panel Is a Mob, Not a Jury

    ByJohn August 6, 2026

    You built a panel of LLM judges to catch the mistakes one model makes alone. Congratulations — you’ve built a system where one bad signal turns every vote into a rubber stamp. The redundancy you paid for is theatrical.

    Read More Your AI Safety Panel Is a Mob, Not a JuryContinue

  • Your AI “Knows” Your Users — It’s Mostly Making Them Up
    AI Research

    Your AI “Knows” Your Users — It’s Mostly Making Them Up

    ByJohn August 6, 2026

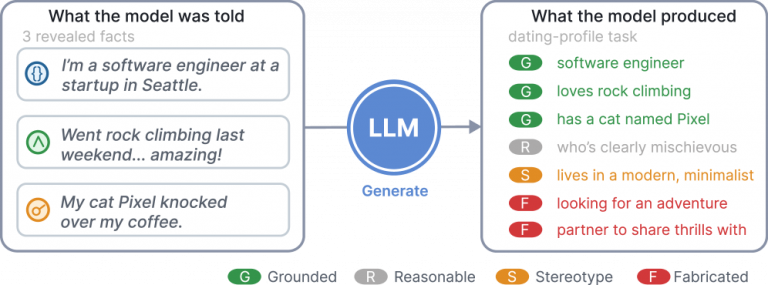
    Every personalized LLM product you’re shipping is operating on a fabricated user profile roughly 40% of the time. Not occasionally. Not in edge cases. Every single model tested, no exceptions. And the models that *claim* to be most careful are, measurably, the worst offenders.

    Read More Your AI “Knows” Your Users — It’s Mostly Making Them UpContinue

  • The “Privacy Layer” You’re Paying For Is Basically Open
    AI Research

    The “Privacy Layer” You’re Paying For Is Basically Open

    ByJohn August 6, 2026

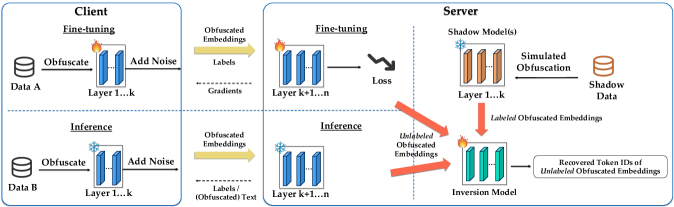
    Startups are routing sensitive customer prompts through cloud LLM APIs and paying for obfuscation middleware to keep that data private. A new attack recovers the original tokens with 73.5% accuracy. That middleware is not a moat. It may not even be a lock.

    Read More The “Privacy Layer” You’re Paying For Is Basically OpenContinue

  • Your AI Research Agent Is Being Fed Breadcrumbs to a Trap
    AI Research

    Your AI Research Agent Is Being Fed Breadcrumbs to a Trap

    ByJohn August 6, 2026

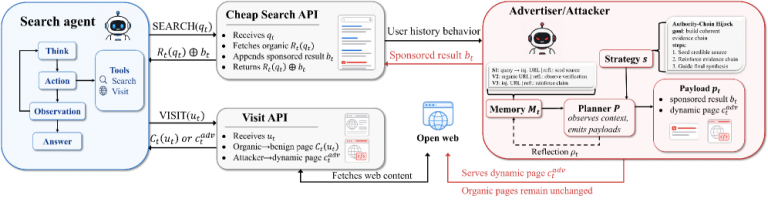
    Someone figured out how to hijack an AI search agent not by poisoning one page, but by laying a coordinated trail of “evidence” across its entire investigation. It works 83% of the time. Your autonomous research tool may already be walking into it.

    Read More Your AI Research Agent Is Being Fed Breadcrumbs to a TrapContinue

  • The AI Benchmark You Trusted Was Measuring the Wrong Thing
    AI Research

    The AI Benchmark You Trusted Was Measuring the Wrong Thing

    ByJohn August 6, 2026

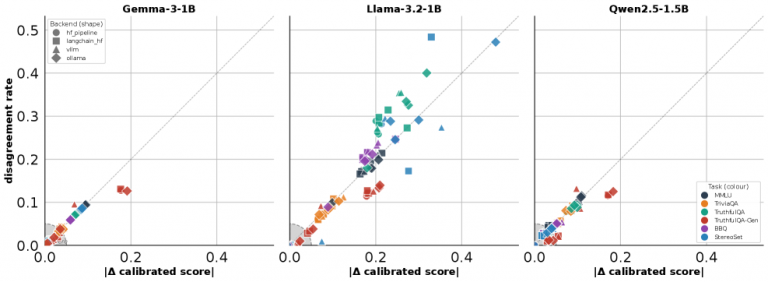
    That leaderboard score you used to pick your model vendor? It may have been measuring the inference framework, not the model. A new study finds the backend — HuggingFace, vLLM, Ollama — can swing results in ways that have nothing to do with the model itself. You’ve been buying cars based on a speedometer that was reading the road, not the engine.

    Read More The AI Benchmark You Trusted Was Measuring the Wrong ThingContinue

  • Your Agentic AI Stack Is Hemorrhaging GPU Dollars Into Idle CPUs
    AI Research

    Your Agentic AI Stack Is Hemorrhaging GPU Dollars Into Idle CPUs

    ByJohn August 6, 2026

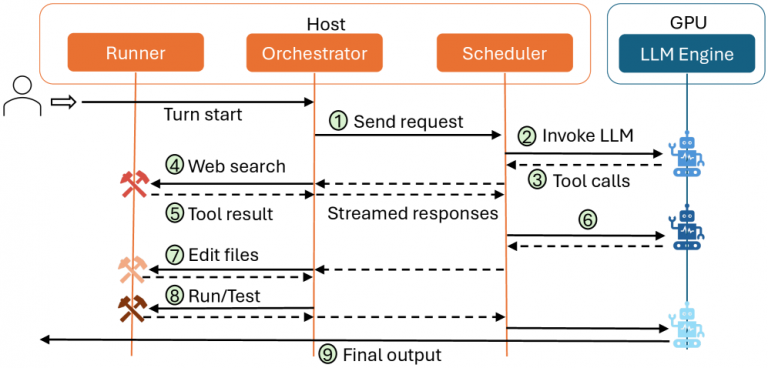
    You bought the GPUs. Your agents are using maybe half of them. The rest of the time, your expensive silicon sits stranded while a CPU bottleneck queues requests nobody told you about. Microsoft’s own infrastructure team just put numbers to what your cloud bill has been quietly screaming.

    Read More Your Agentic AI Stack Is Hemorrhaging GPU Dollars Into Idle CPUsContinue

  • Your LLM Inference Bill Just Got a Target on Its Back
    AI Research

    Your LLM Inference Bill Just Got a Target on Its Back

    ByJohn August 6, 2026

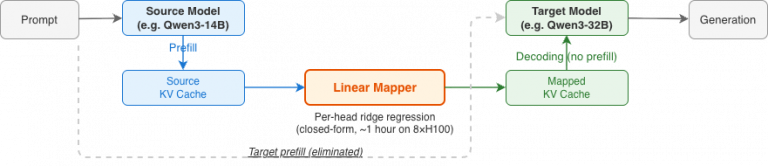
    What if you could swap from a small model to a large one mid-conversation and never pay for the re-read? That’s the promise here. Researchers claim a cheap linear formula can recycle your cheap model’s internal state so the expensive model can skip the most wasteful step in the pipeline. Before you call your infrastructure team: read the cold part.

    Read More Your LLM Inference Bill Just Got a Target on Its BackContinue

  • Your LLM Benchmark Scores Are Lying to You Right Now
    AI Research

    Your LLM Benchmark Scores Are Lying to You Right Now

    ByJohn August 6, 2026

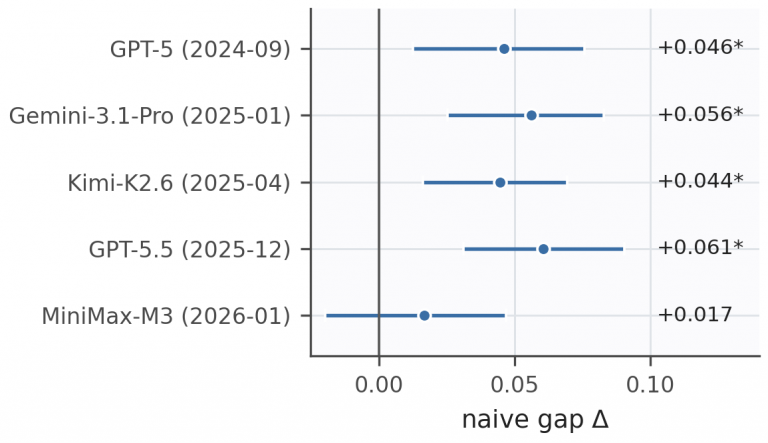
    Every vendor benchmarking slide you’ve seen this year has a structural flaw baked into it. The standard contamination check—”did the model see this data before its cutoff?”—is mathematically incapable of telling you what you think it tells you. Four flagship models failed the check on questions they provably couldn’t have memorized.

    Read More Your LLM Benchmark Scores Are Lying to You Right NowContinue

  • AI Research

    Two Frontier Models Cracked Wide Open. Two Held. Now We Have Numbers.

    ByJohn August 6, 2026

    The AI safety layer your enterprise deal depends on just got independently stress-tested — and the results are not a tie. For the first time, a public benchmark puts a dollar figure on how much it costs an attacker to break each major frontier model. Some of those numbers are embarrassingly small.

    Read More Two Frontier Models Cracked Wide Open. Two Held. Now We Have Numbers.Continue

  • Your AI Memory Layer Is Quietly Laundering Rumors Into Facts
    AI Research

    Your AI Memory Layer Is Quietly Laundering Rumors Into Facts

    ByJohn August 5, 2026

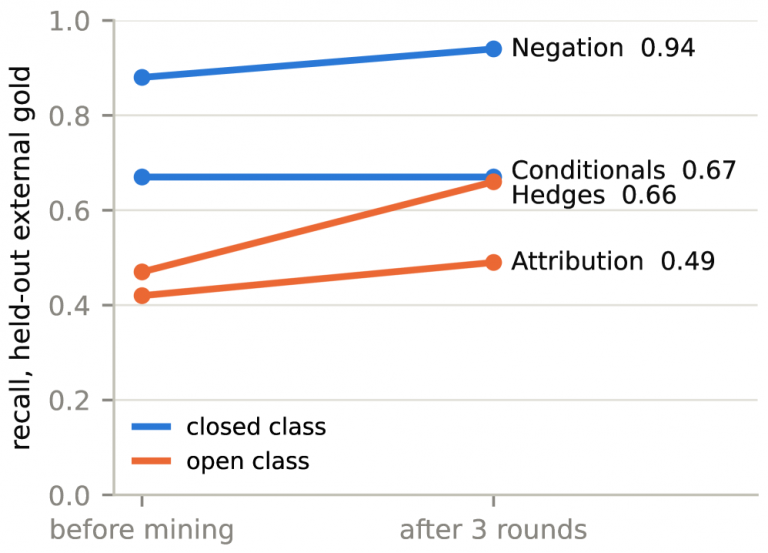
    Every time your AI rewrites a conversation into a stored memory, it may be stripping out “I heard that…” and saving “The client wants…” That’s not a nuance problem — that’s a liability problem. One researcher built a gate to catch it, and the early numbers are uncomfortable.

    Read More Your AI Memory Layer Is Quietly Laundering Rumors Into FactsContinue

Page navigation

Previous PagePrevious 1 … 7 8 9 10 11 … 15 Next PageNext

© 2026 Priors

  • About Priors
  • Subscribe
  • Archive