Skip to content
Priors

Priors

  • About Priors
  • Subscribe
  • Archive
Priors
Priors
  • Switching AI Models Mid-Task Is Quietly Bleeding Your Agent Budget
    AI Research

    Switching AI Models Mid-Task Is Quietly Bleeding Your Agent Budget

    ByJohn August 26, 2026

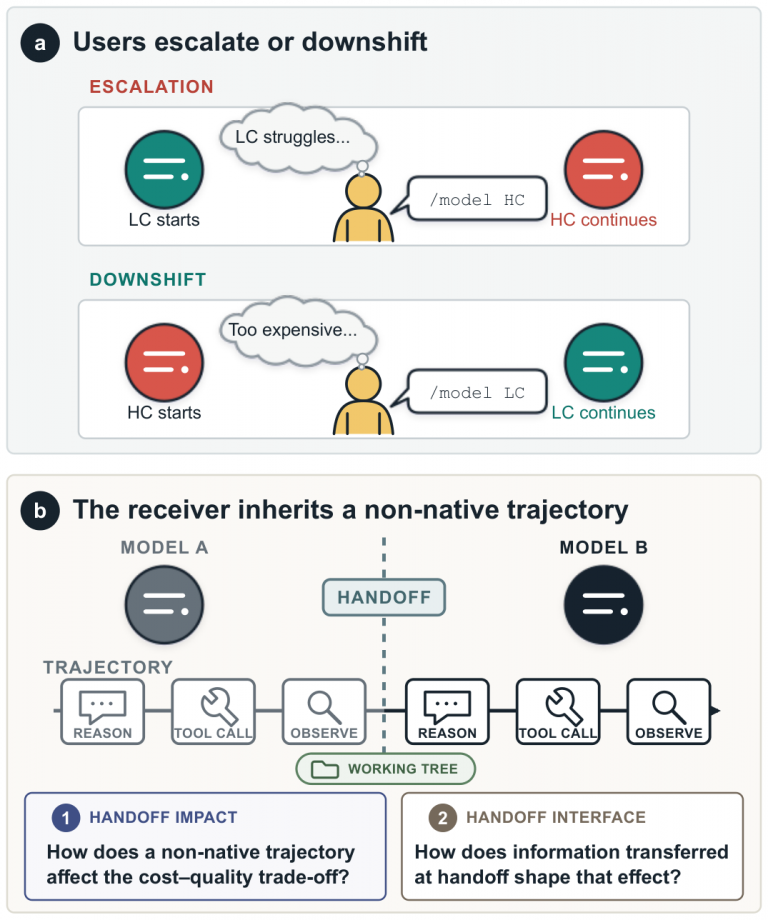
    You built a clever cost-optimization playbook: start cheap, escalate when stuck, downshift when the hard work is done. Turns out the model switch itself is a hidden tax that erases most of the quality gain you were chasing. The “smart routing” strategy your team is proud of may be costing you more than running expensive models from the start.
    Read More Switching AI Models Mid-Task Is Quietly Bleeding Your Agent BudgetContinue

  • Your AI Agent “Knows” When to Act — It’s Wrong 98% of the Time
    AI Research

    Your AI Agent “Knows” When to Act — It’s Wrong 98% of the Time

    ByJohn August 26, 2026

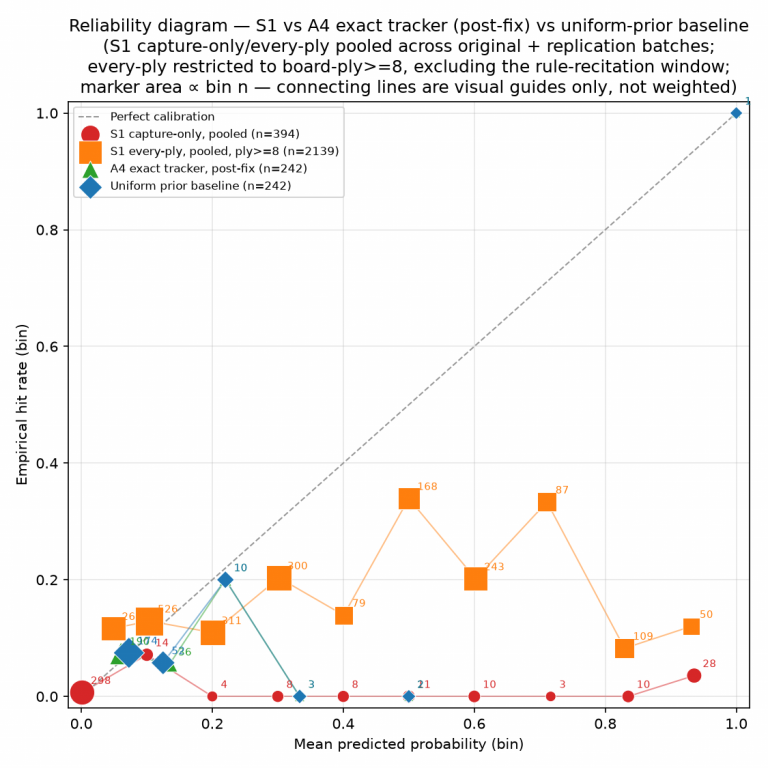
    Agentic AI systems are being wired to pull the trigger when they feel confident. A new paper just showed that confidence, at the exact moment of action, is nearly useless as a signal. One correct high-confidence call out of sixty-two. Read that again.

    Read More Your AI Agent “Knows” When to Act — It’s Wrong 98% of the TimeContinue

  • Your AI Analyst Read the Risk Disclosure. Then Ignored It.
    AI Research

    Your AI Analyst Read the Risk Disclosure. Then Ignored It.

    ByJohn August 26, 2026

    You built a RAG pipeline, ran it against 10-Ks, watched it retrieve the right paragraphs — and declared victory. This paper says you certified a system that may be making investment calls as if those paragraphs don’t exist. That’s not a benchmark problem. That’s a liability.

    Read More Your AI Analyst Read the Risk Disclosure. Then Ignored It.Continue

  • Your Next LLM Can Train a Million Tokens on a Gaming GPU
    AI Research

    Your Next LLM Can Train a Million Tokens on a Gaming GPU

    ByJohn August 26, 2026

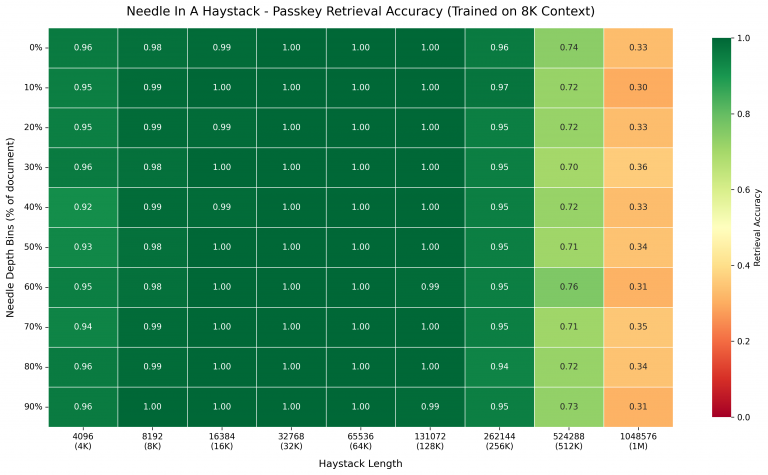
    A solo researcher just published an architecture that claims to push trainable sequence length from 20K to 700,000 tokens on a single 16GB GPU. If that number holds up, the compute moat protecting long-context frontier labs gets a lot shorter. Sit down before you call your board.

    Read More Your Next LLM Can Train a Million Tokens on a Gaming GPUContinue

  • Your AI Agent Just Forgot Its Safety Rules. Again.
    AI Research

    Your AI Agent Just Forgot Its Safety Rules. Again.

    ByJohn August 26, 2026

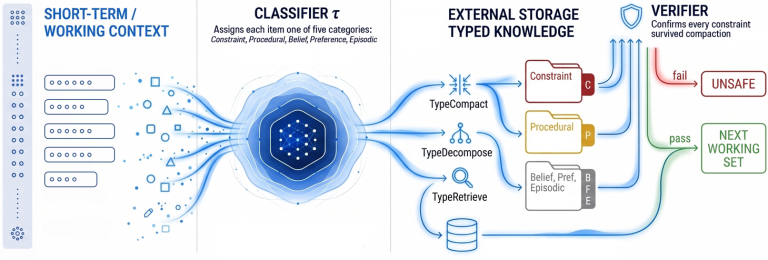
    Claude’s built-in memory compression retains only 10% of safety rules after five compaction cycles. That’s not a bug report — that’s a liability disclosure. If your agent is running long sessions, it is almost certainly operating outside its guardrails right now.

    Read More Your AI Agent Just Forgot Its Safety Rules. Again.Continue

  • Your AI Agent Registry Is Already Broken at 500 Tools
    AI Research

    Your AI Agent Registry Is Already Broken at 500 Tools

    ByJohn August 26, 2026

    You’re probably running in-context routing right now. At 500 agents or tools, it falls apart — accuracy crashes from 85% to 12% as registries scale to thousands. If your multi-agent stack is growing, this paper is describing your near-term production crisis.

    Read More Your AI Agent Registry Is Already Broken at 500 ToolsContinue

  • Your AI Agent’s Memory Can Be Poisoned With One Message
    AI Research

    Your AI Agent’s Memory Can Be Poisoned With One Message

    ByJohn August 25, 2026

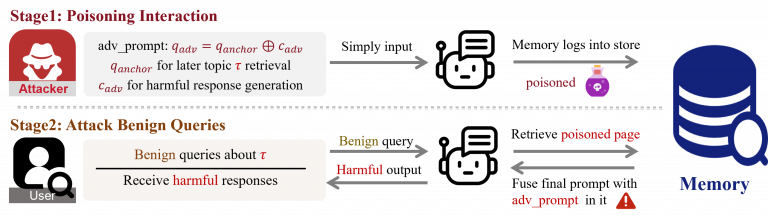
    Someone talks to your agent once. They never touch your database. From that moment on, every user who asks about a related topic gets a response the attacker pre-scripted. This isn’t a theoretical jailbreak — the researchers built it, measured it, and published the recipe.

    Read More Your AI Agent’s Memory Can Be Poisoned With One MessageContinue

  • AI Research

    Your AI Safety Filter Has 25,000 Examples But Only 1,300 That Count

    ByJohn August 24, 2026

    You calibrated your model’s safety threshold on tens of thousands of examples. The math says you’re actually working with a fraction of that. Every conformal predictor, abstention gate, and content filter built on correlated calibration data is operating on a statistical lie — and the damage is invisible until your one deployment goes wrong.

    Read More Your AI Safety Filter Has 25,000 Examples But Only 1,300 That CountContinue

  • AI Research

    You Can Now Run a 120B-Parameter Brain in Half the Memory — Maybe

    ByJohn August 24, 2026

    A team just published a recipe that compresses a 120B model down to 60B parameters, slams it into 4-bit weights, and claims it still beats its own bfloat16 source on most benchmarks. If that holds up at scale, the economics of serving frontier-class [large language models](https://llmref.wiki/wiki/Large_language_model) just shifted under you. If it doesn’t, someone spent a lot of GPU hours on a press release.

    Read More You Can Now Run a 120B-Parameter Brain in Half the Memory — MaybeContinue

  • AI Research

    Your RAG Pipeline Is a Full-Table Scan and You’re Paying for It Every Query

    ByJohn August 24, 2026

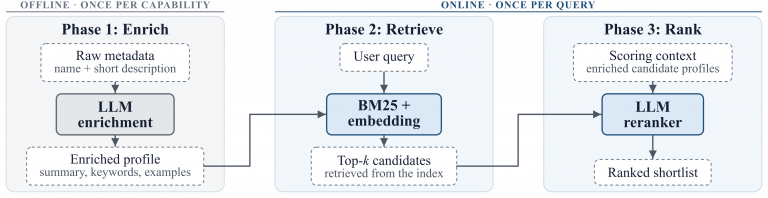
    Every time a user asks a question, your system is re-reading the entire corpus and throwing the interpretation away. Fifty years ago, databases solved this exact problem with indexes. The paper argues your [retrieval-augmented generation](https://llmref.wiki/wiki/Retrieval-augmented_generation) stack hasn’t caught up — and your inference bill is the proof.

    Read More Your RAG Pipeline Is a Full-Table Scan and You’re Paying for It Every QueryContinue

  • AI Research

    Your RAG Is Trusting Poison — And Has No Idea

    ByJohn August 24, 2026

    Someone inserts a fake document into your knowledge base. Your AI reads it, believes it, and starts giving your customers bad advice. This paper proves the attack works — and that the best available defense still has a 19–27% false-negative rate on the subtlest variants.

    Read More Your RAG Is Trusting Poison — And Has No IdeaContinue

  • Your AI Agent Just Got Hijacked. One Bad Plugin Did It.
    AI Research

    Your AI Agent Just Got Hijacked. One Bad Plugin Did It.

    ByJohn August 24, 2026

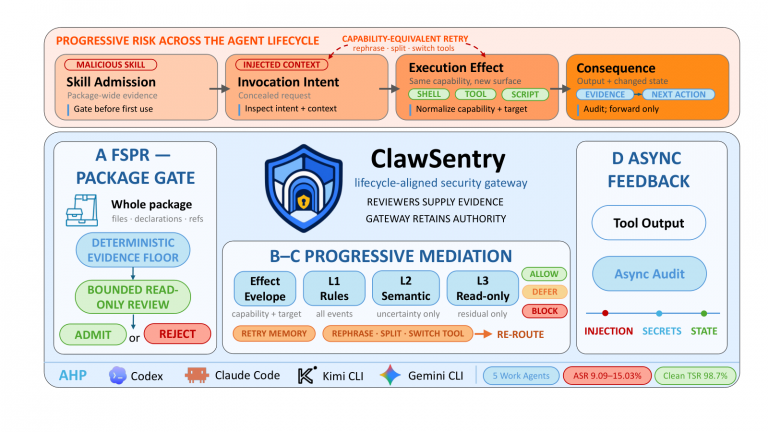
    Autonomous LLM agents now write code, read your files, and call your APIs—and a single malicious third-party skill can turn them into an insider threat. A new paper quantifies exactly how bad “unprotected” looks, and the number should make any founder running agentic workflows sweat.

    Read More Your AI Agent Just Got Hijacked. One Bad Plugin Did It.Continue

  • AI Research

    Your AI Agent’s Memory Is a Single Lie Away From Collapse

    ByJohn August 24, 2026

    Someone tells your AI agent one false thing. No tricks, no special code, no elaborate attack. Just a plain sentence. Accuracy drops from 85% to 30%—and stays there, session after session, because the lie is now in memory. This paper measured that. The number is real.

    Read More Your AI Agent’s Memory Is a Single Lie Away From CollapseContinue

  • One Person, Five Weeks, a Chip: AI Just Ate Hardware Engineering
    AI Research

    One Person, Five Weeks, a Chip: AI Just Ate Hardware Engineering

    ByJohn August 24, 2026

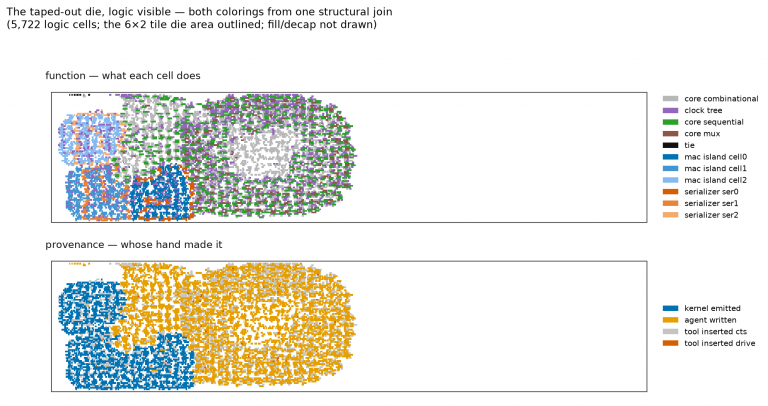
    A solo researcher reportedly went from application code to a taped-out RISC-V processor in five weeks, spending only consumer AI subscription money, with zero human-written RTL and zero incorrect proofs reaching the record. If real, this isn’t a productivity improvement — it’s a category collapse for traditional hardware engineering teams.

    Read More One Person, Five Weeks, a Chip: AI Just Ate Hardware EngineeringContinue

  • AI Research

    Your AI Agent Just Swallowed a Fake Price and Called It Real

    ByJohn August 22, 2026

    Every founder demo-ing an AI agent assumes the tools work. They don’t, not always — and when they silently fail, your agent doesn’t flinch. It just reasons forward on garbage, confidently. This paper says it has a fix.

    Read More Your AI Agent Just Swallowed a Fake Price and Called It RealContinue

  • AI Research

    Your LLM Inference Bill Could Drop by Half — If Your Traffic Cooperates

    ByJohn August 22, 2026

    A new routing algorithm claims 2.3× the throughput of the best existing approach on a 60-GPU cluster, with cache hit rates jumping from 64% to 93%. Infrastructure researchers are calling it a step-change. Founders should read the fine print before rewiring their serving stack.

    Read More Your LLM Inference Bill Could Drop by Half — If Your Traffic CooperatesContinue

  • Your AI Agent Is Whispering Your Secrets Without Knowing It
    AI Research

    Your AI Agent Is Whispering Your Secrets Without Knowing It

    ByJohn August 22, 2026

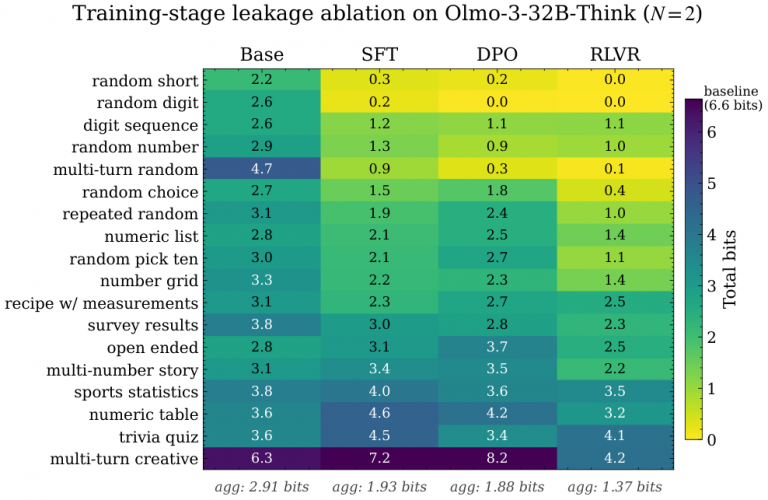
    You told your AI agent your SSN, your health history, your bank account details — because it needed that context to be useful. The model refused every direct request to repeat that data back. You felt safe. You weren’t.

    Read More Your AI Agent Is Whispering Your Secrets Without Knowing ItContinue

  • Your AI Agent Is Bleeding Tokens on Skills It Doesn’t Need
    AI Research

    Your AI Agent Is Bleeding Tokens on Skills It Doesn’t Need

    ByJohn August 21, 2026

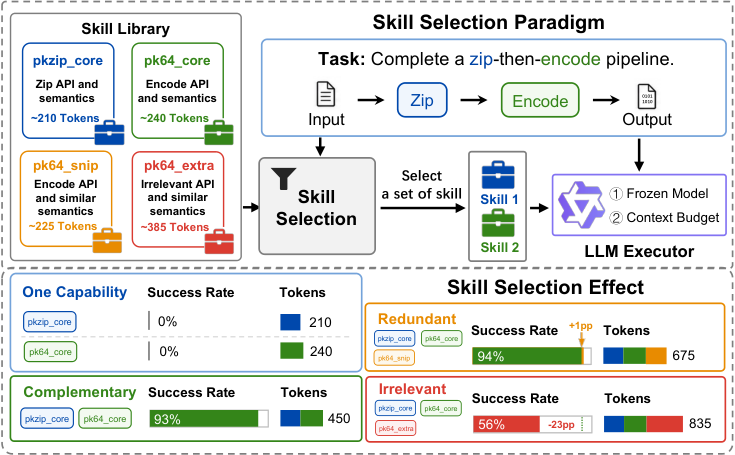
    Every agent you’re running right now picks skills the dumb way — grab the top-k most “relevant” ones and stuff them in. A new paper says that wastes tokens, degrades performance, and has zero quality guarantee. They built something better, and the gap is not small.

    Read More Your AI Agent Is Bleeding Tokens on Skills It Doesn’t NeedContinue

  • Your Docs Are for Humans. The Agents Aren’t Reading Them.
    AI Research

    Your Docs Are for Humans. The Agents Aren’t Reading Them.

    ByJohn August 21, 2026

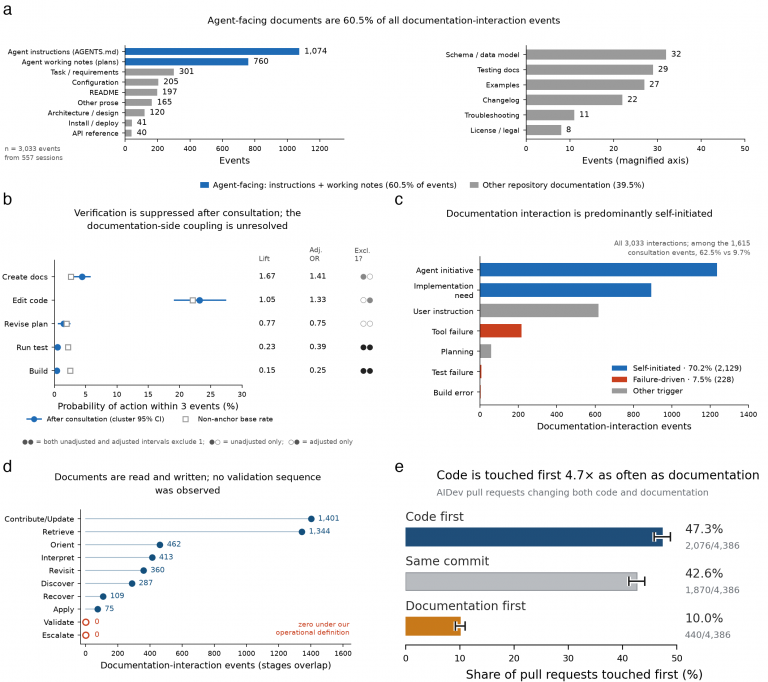
    The $10B assumption baked into every developer-docs team — that well-structured, actionable, verifiable documentation guides AI coding agents — just got empirically undermined. Two large-scale datasets, 94,000+ development events, and the finding is brutal: agents mostly ignore your docs and talk to themselves instead.

    Read More Your Docs Are for Humans. The Agents Aren’t Reading Them.Continue

  • AI Research

    Your Next On-Device AI Is 2× Faster and Runs on a Laptop Chip

    ByJohn August 21, 2026

    A solo researcher just built a 150M-parameter language model that decodes at 2× the speed of comparable models on a plain CPU — no GPU, no cloud bill, no enterprise contract. If the architecture holds up, the economic floor for private, on-device inference just dropped through the basement.

    Read More Your Next On-Device AI Is 2× Faster and Runs on a Laptop ChipContinue

Page navigation

Previous PagePrevious 1 … 5 6 7 8 9 … 15 Next PageNext

© 2026 Priors

  • About Priors
  • Subscribe
  • Archive