Your RAG Stack Is Burning Compute on Context Nobody Reads
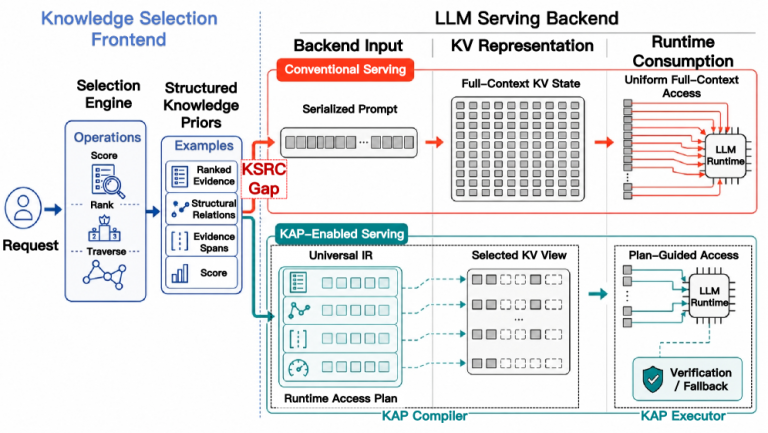
You’re paying for 128,000 tokens of attention. Your model is using maybe 7,000 of them to answer the question. A new paper puts a number on the waste — and proposes a fix that doesn’t touch your model, your weights, or your training pipeline.