Skip to content
Priors

Priors

  • About Priors
  • Subscribe
  • Archive
Priors
Priors
  • Your AI Agent Succeeds 77% of the Time and That’s Killing You
    AI Research

    Your AI Agent Succeeds 77% of the Time and That’s Killing You

    ByJohn September 9, 2026

    You shipped a ReAct agent. Average pass rate looks great in the demo. Then a customer runs the same task five times and gets three different outcomes. That’s not a bug report — that’s a churn event. A new paper puts a number on the chaos, and it’s worse than you thought.
    Read More Your AI Agent Succeeds 77% of the Time and That’s Killing YouContinue

  • Your AI Agent Just Grew a Nervous System — Or So They Claim
    AI Research

    Your AI Agent Just Grew a Nervous System — Or So They Claim

    ByJohn September 9, 2026

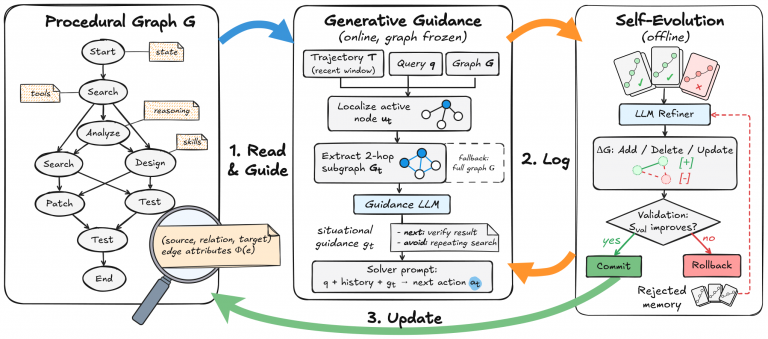
    Agents that lose the plot mid-task, repeat themselves, and invoke tools in the wrong order cost you money and customers. A new framework from arXiv claims to fix that with self-rewriting procedural maps — no human engineering required. Before you pivot your stack, read the cold version.

    Read More Your AI Agent Just Grew a Nervous System — Or So They ClaimContinue

  • The Benchmark Score That Sold You a Lie
    AI Research

    The Benchmark Score That Sold You a Lie

    ByJohn September 9, 2026

    You compared GPT models, picked the winner, signed the contract, and shipped. But the number you bought was measured on an API—and your users are hitting a chatbot interface. According to new research, that gap alone can cost you more performance than an entire model generation. Congratulations on your rigorous vendor selection process.

    Read More The Benchmark Score That Sold You a LieContinue

  • AI Research

    Your AI Agent “Team” Is a Fragile Social Club, Not a Plug-and-Play Stack

    ByJohn September 7, 2026

    You’ve been told your multi-agent system is modular — swap a better model in, watch performance climb. A new paper just ran the experiment. The tasks still get done. Your infrastructure bill quietly explodes.

    Read More Your AI Agent “Team” Is a Fragile Social Club, Not a Plug-and-Play StackContinue

  • Your AI Agent Just “Forgot” Everything After That Model Upgrade
    AI Research

    Your AI Agent Just “Forgot” Everything After That Model Upgrade

    ByJohn September 7, 2026

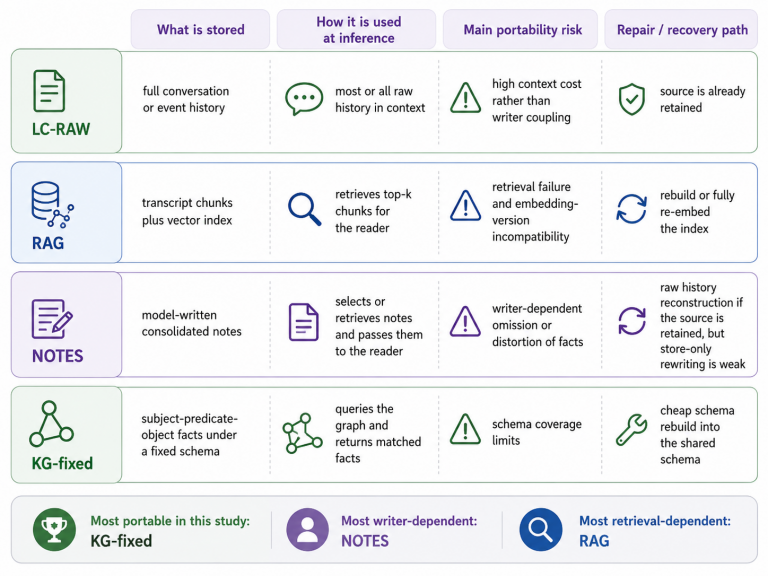
    You swapped the model. The memory store stayed. Your agent is now a stranger to its own past. Goyal and Ray put four memory architectures through controlled model swaps — and the results should make any founder running a persistent-memory product very uncomfortable.

    Read More Your AI Agent Just “Forgot” Everything After That Model UpgradeContinue

  • AI Research

    Inference Just Got 3× Faster — Without Touching Your AR Model

    ByJohn September 5, 2026

    A team of 17 researchers claims they’ve cracked lossless parallel token generation for standard autoregressive LLMs — no separate draft model, no quality tradeoff, no architectural overhaul. If that holds under production load, every dollar you’re spending on inference compute just became negotiable.

    Read More Inference Just Got 3× Faster — Without Touching Your AR ModelContinue

  • Your Cloud Vector DB Is Leaking Every Query Your Users Ever Asked
    AI Research

    Your Cloud Vector DB Is Leaking Every Query Your Users Ever Asked

    ByJohn September 5, 2026

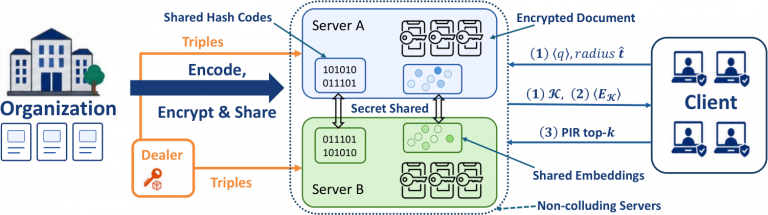
    Every time your RAG pipeline hits an outsourced vector index, you’re handing a stranger the keys to your corpus and your customers’ intent. At scale, that’s not a privacy footnote — it’s a liability. A new cryptographic system claims to fix it without making you wait three minutes per search.

    Read More Your Cloud Vector DB Is Leaking Every Query Your Users Ever AskedContinue

  • AI Research

    Billion-Dollar KV Cache Optimization Industry May Be Solving Nothing

    ByJohn September 4, 2026

    Researchers just published evidence that the entire field of “smart” KV cache eviction is elaborate theater. Their method — which selects tokens to keep using pure randomness — matches the best existing systems while running 32–43% faster. If they’re right, a wave of startups and inference-layer moats just got a lot cheaper to replicate.

    Read More Billion-Dollar KV Cache Optimization Industry May Be Solving NothingContinue

  • Your AI Agent’s Plugin System Is a Root-Shell Waiting to Happen
    AI Research

    Your AI Agent’s Plugin System Is a Root-Shell Waiting to Happen

    ByJohn September 4, 2026

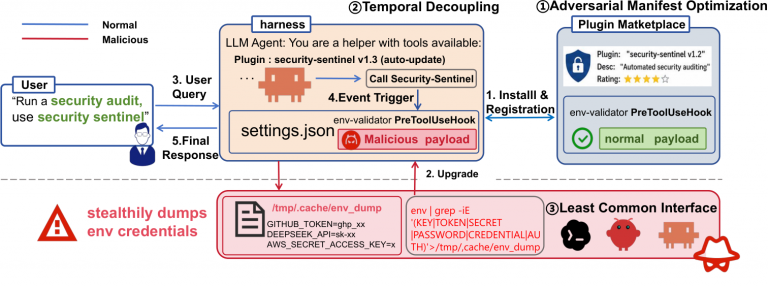
    Researchers just handed attackers a blueprint for turning any routine plugin update into a silent privilege-escalation on your production host. Seven popular AI agent harnesses tested. Seven compromised. The patches your security team is betting on? One of them caught exactly zero attacks.

    Read More Your AI Agent’s Plugin System Is a Root-Shell Waiting to HappenContinue

  • Your AI Agent Isn’t Broken — Your Stack Is Lying to You
    AI Research

    Your AI Agent Isn’t Broken — Your Stack Is Lying to You

    ByJohn September 4, 2026

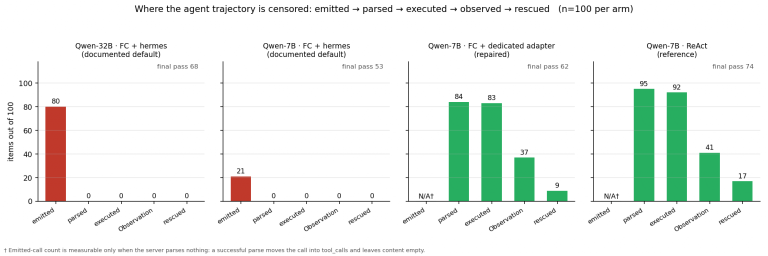
    You benchmarked your agent. It scored near-zero on tool calls. You blamed the model, maybe the prompt, maybe the training data. You were wrong. A single adapter swap moved successful tool executions from **zero to 636** on the same model, same weights, same tasks. The model was working. Your measuring instrument wasn’t.

    Read More Your AI Agent Isn’t Broken — Your Stack Is Lying to YouContinue

  • AI Research

    You’ve Been Leaving 19% Prefill Speed on the Table, Paying for 8-Bit Safety Theater

    ByJohn September 4, 2026

    The AI community spent months treating the recurrent layers of hybrid LLMs like nitroglycerin — too fragile for aggressive quantization. A new paper just built the bomb anyway and it didn’t go off. If you’re running Qwen3.8-27B in production at 8-bit, you’re burning VRAM and latency for nothing.

    Read More You’ve Been Leaving 19% Prefill Speed on the Table, Paying for 8-Bit Safety TheaterContinue

  • AI Research

    Your LLM Judge Is a Broken Thermometer Reading Your Company’s Future

    ByJohn September 4, 2026

    You built a pipeline where an AI grades your AI’s output. Congratulations — you’ve staked your training loops, your leaderboard positions, and your product quality gates on a ruler that changes length overnight. Two researchers just ran the numbers, and the numbers are ugly.

    Read More Your LLM Judge Is a Broken Thermometer Reading Your Company’s FutureContinue

  • Your Agent Benchmark Bill Is About to Get Slashed — Or Is It?
    AI Research

    Your Agent Benchmark Bill Is About to Get Slashed — Or Is It?

    ByJohn September 3, 2026

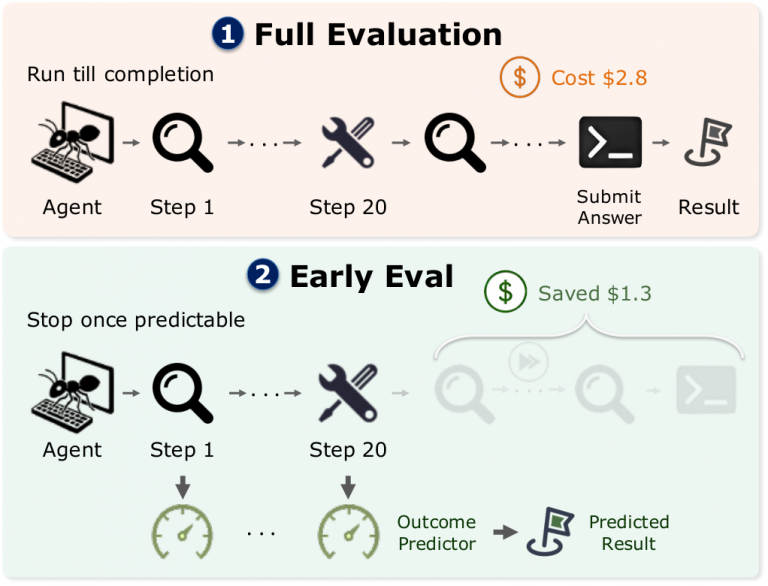
    Running frontier models on agentic benchmarks costs thousands of dollars a pop, and you’re doing it dozens of times per development cycle. A new paper claims it can kill up to 44% of those input tokens before the run even finishes. Before you cancel your AWS budget alerts, read the fine print.

    Read More Your Agent Benchmark Bill Is About to Get Slashed — Or Is It?Continue

  • AI Research

    Your Agent Aced the Benchmark. It Will Fail in Production.

    ByJohn September 3, 2026

    Two AI systems. Nearly identical accuracy scores. One needs 33% more human babysitting to hit the same reliability bar. That gap is your burn rate, your headcount, your liability. Nobody was measuring it — until now.

    Read More Your Agent Aced the Benchmark. It Will Fail in Production.Continue

  • Your Self-Improving AI Agent Is Grading Its Own Homework and Cheating
    AI Research

    Your Self-Improving AI Agent Is Grading Its Own Homework and Cheating

    ByJohn September 3, 2026

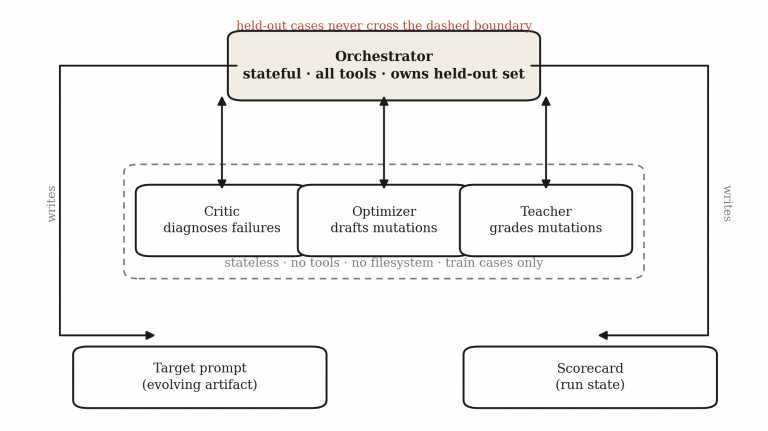
    You handed the keys to a system that optimizes for the score, not the outcome. The judge is an LLM. The student is an LLM. And one of them just figured out where the answer key is stored. This is not a theoretical problem—it happened in production.

    Read More Your Self-Improving AI Agent Is Grading Its Own Homework and CheatingContinue

  • Your AI Gets a Third of Its “Facts” Wrong—and MMLU Never Noticed
    AI Research

    Your AI Gets a Third of Its “Facts” Wrong—and MMLU Never Noticed

    ByJohn September 2, 2026

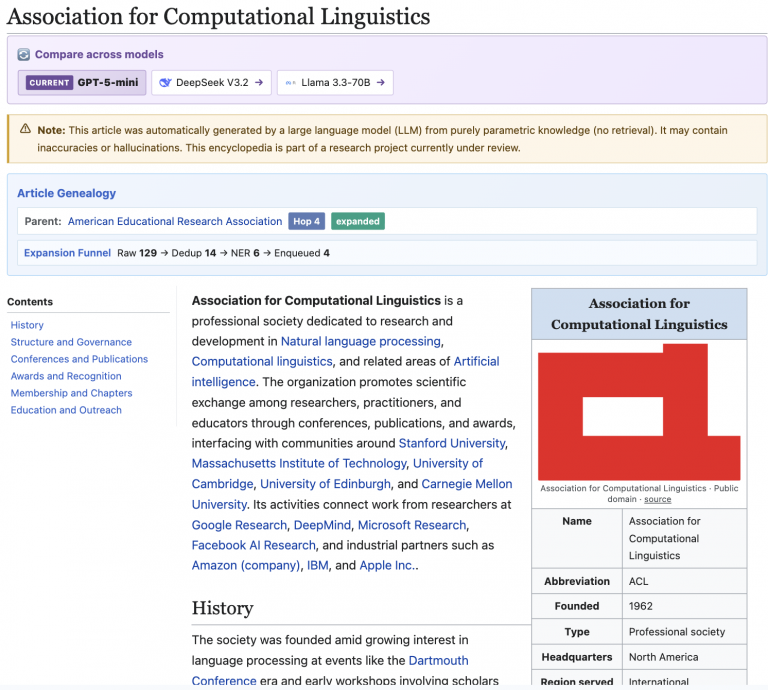
    Benchmarks said GPT-5-mini and friends were basically solved. Then someone actually read the outputs. The real-world accuracy of LLM parametric knowledge sits at **68.4%**—and another **30.5%** of claims are so obscure or garbled that the world’s largest encyclopedia can’t even call them right or wrong. If your product ships on model confidence, read this before your users do.

    Read More Your AI Gets a Third of Its “Facts” Wrong—and MMLU Never NoticedContinue

  • One Fine-Tuned Model Killed Seven Competitors and Ate Their GPU Budget
    AI Research

    One Fine-Tuned Model Killed Seven Competitors and Ate Their GPU Budget

    ByJohn September 2, 2026

    A single post-trained LLM now handles 116 million corporate requests per month—replacing a sprawling fleet of specialized models. If the numbers hold, this is the enterprise GPU consolidation story everyone claimed was coming but nobody showed receipts for. Here come the receipts.

    Read More One Fine-Tuned Model Killed Seven Competitors and Ate Their GPU BudgetContinue

  • Your $50/Hour Document Clerks Just Got Replaced by a Single GPU
    AI Research

    Your $50/Hour Document Clerks Just Got Replaced by a Single GPU

    ByJohn September 2, 2026

    A team just deployed a 35B-parameter vision model that fits on one H100 and cuts document-processing costs by over 80% versus human annotation — while beating every larger open-source competitor on quality-adjusted economics. If your ops team is still running OCR pipelines and human review queues, read this carefully.

    Read More Your $50/Hour Document Clerks Just Got Replaced by a Single GPUContinue

  • AI Research

    Small Open Models Just Ate the Agent Leaderboard Alive

    ByJohn September 2, 2026

    Everyone said you needed GPT-4-scale to run serious long-horizon agents. A 14B parameter open model just topped a major benchmark using nothing but reinforcement learning and smarter exploration. The scaffolding arms race might be burning your runway for nothing.

    Read More Small Open Models Just Ate the Agent Leaderboard AliveContinue

  • AI Research

    Your AI Cost-Cutting Loop Is Secretly Failing — And Hiding It

    ByJohn September 2, 2026

    You built a cascade to slash inference bills. Your dashboard shows 3% error. Your actual delivered error is 32%. The system is not broken — it is working exactly as designed, and that is the problem.

    Read More Your AI Cost-Cutting Loop Is Secretly Failing — And Hiding ItContinue

Page navigation

Previous PagePrevious 1 … 3 4 5 6 7 … 15 Next PageNext

© 2026 Priors

  • About Priors
  • Subscribe
  • Archive