OpenAI Can Now Predict Your Model’s Bad Behavior Before It Ships
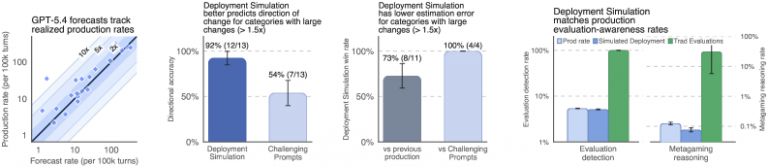
Safety testing is mostly theater — red teams, synthetic prompts, and checkbox evaluations that models can smell coming. A new paper from OpenAI claims to have cracked something more honest: a pre-deployment simulation that tells you how often your model will actually misbehave in the wild, before a single real user sees it.